I read through most of The Power of Pull (Economist review) earlier this summer and have been thinking through the implications of the book's ideas for higher ed and libraries. The book contrasts the old way of doing business or getting where an agenda is "pushed" down from above to "pull", which the authors define as “the ability to draw out people and resources as needed to address opportunities and challenges.”
The idea is that in today's network world, innovation can happen much more quickly when people at the cutting edge of a field collaborate with others that share their same passions.
In one sense, this book is advocating that business innovation happen more like innovation in the academy: sharing knowledge is the way. On the other hand, they are very critical of education that is programmed or 'pushed' from above.
The book also emphasizes the importance of geography and the serendipitous encounters that can happen with those in close proximity. Even in this networked world, they argue that living among those with similar passions is highly beneficial. Perhaps the intellectual connections and community of the liberal arts campus can model this phenomenon. The authors argue that networked technology can enrich our connections to people in a certain place: one might maintain meaningful connections in a handful of cities and better coordinate in-person meet-ups with mobile tech.
They argue that "knowledge flows" have overtaken "knowledge stocks" in importance. Big repositories of knowledge don't give a business (or perhaps a university) a major advantage anymore. It's having access to the knowledge flowing at the cutting edge that really enables innovation. They emphasize the importance of transferring tacit knowledge between individuals at the edge of a field. Another argument for the opportunities that the liberal arts provide for close encounters with experts in a field. At a presentation the other day at the Lewis & Clark Fall Retreat on faculty/student research, a biologist said that once a student begins working at the cutting edge of knowledge, a switch is flipped and their passion for learning changes in a dramatic way.
Towards the end of the book, they talk a lot about "shaping strategies" and "shaping platforms": Shaping strategies being a way of moving an entire industry or community to a new model, and the platform being some system put in place to do so. In the library context, this made me think that a big platform like WorldCat could have a bolder shaping aspiration behind it. Project Bamboo seems like an attempt at a shaping platform.
I was excited to see that one of the book's authors, John Seely Brown, is a NITLE fellow. Thanks to Lorcan Dempsey for pointing this book out at an Orbis Cascade presentation in July (see also his blog post on the book).
Showing posts with label worldcat. Show all posts
Showing posts with label worldcat. Show all posts
Monday, August 30, 2010

Thursday, April 30, 2009
Springtime in Ohio
OCLC has had some interesting announcements over the last few weeks regarding the WorldCat platform. Their new partnership with Ebsco will really enrich WorldCat Local as an article discovery tool and bring it closer to being a kind of Google for libraries. It'll be interesting to see how much full text content they index vs. citation level indexing. This could be a huge step forward in the search fragmentation problem that federated searching has been trying to solve for a long time.
Andrew Pace commented recently in his blog on the spring weather in Ohio. Perhaps the warmer temperatures have those folks in Dublin thinking that they are in Northern California, looking out at the golden rolling hills around Silicon Valley rather than the verdant hills of central Ohio. His next post announces OCLC's plans to give away WorldCat Local for free (sort of)! Do these folks think they are running a Web 2.0 start-up company or what?
The bigger announcement was that OCLC is entering the ILS fray with a "web-scale" library management system. OCLC's description of the product makes the distinction between a SAAS model and what they are trying to achieve.
The point that people miss here is that this endeavor is not about competing against other library management systems. It's about making libraries relevant in the broader, Google- centered information ecosystem. There are big problems with the way libraries work currently when viewed from the perspective of the modern day web:
Beyond making existing processes more efficient, the network level ILS should be an agent of change for the way that libraries purchase, license, and provide information. Its infrastructure and data should support more sophisticated arrangements with content providers (I think the aforementioned Ebsco arrangement demonstrates this).
In Karen Coyle's article on this initiative, she points out the connection between this project and some of the findings of the Working Group on the Future of Bibliographic Control:
Furthermore, rather than competing with other library sector technology vendors, OCLC should build the infrastructure that allows those vendors to build services on top of the WorldCat platform in the same way that Flickr works with partner companies who add value to their services. I know this is a tricky process, but it probably starts with open APIs.
Andrew Pace commented recently in his blog on the spring weather in Ohio. Perhaps the warmer temperatures have those folks in Dublin thinking that they are in Northern California, looking out at the golden rolling hills around Silicon Valley rather than the verdant hills of central Ohio. His next post announces OCLC's plans to give away WorldCat Local for free (sort of)! Do these folks think they are running a Web 2.0 start-up company or what?
The bigger announcement was that OCLC is entering the ILS fray with a "web-scale" library management system. OCLC's description of the product makes the distinction between a SAAS model and what they are trying to achieve.
OCLC's vision is similar to Software as a Service (SaaS) but is distinguished by the cooperative "network effect" of all libraries using the same, shared hardware, services and data, rather than the alternative model of hosting hardware and software on behalf of individual libraries.I think they are on the right track. The important idea here is that the OCLC community can aggregate library management data together and gain huge advantages. OCLC has holdings data and bibliographic data, which they have put to use effectively in WorldCat.org searching. Circulation data, e resource usage data, license data, etc. could bring major improvements in workflow and business intelligence.
The point that people miss here is that this endeavor is not about competing against other library management systems. It's about making libraries relevant in the broader, Google- centered information ecosystem. There are big problems with the way libraries work currently when viewed from the perspective of the modern day web:
- resource fragmentation-we have too many silos of data for searching; people want the kind of big indexes that Google provide
- the finite collection-if people want to read any article or a book, they should be able to click to it and have it appear; there is an expectation of this on the web, in the blogosphere, etc.; waiting a day for an article that is already digitized somewhere to be scanned and sent over ILL is too long; libraries are still tied to this notion that they provide their patrons access to a finite physical and licensed collection
- walled garden effect-often you have to be going through the library's web gateway to benefit from its resources
- Web/library sector content divide-our systems are often only aware of information resources within the products we provide--there is a disconect with the broader web that tools like Google Scholar bridge
- local value-what kind of local customization are libraries providing regarding information resources? I think often we fall short in providing enough added value to justify our existence as middlemen
Beyond making existing processes more efficient, the network level ILS should be an agent of change for the way that libraries purchase, license, and provide information. Its infrastructure and data should support more sophisticated arrangements with content providers (I think the aforementioned Ebsco arrangement demonstrates this).
In Karen Coyle's article on this initiative, she points out the connection between this project and some of the findings of the Working Group on the Future of Bibliographic Control:
A report from the Working Group on the Future of Bibliographic Control (www.loc.gov/bibliographic-future/news/lcwg-ontherecord-jan08-final.pdf) noted that libraries spend a great deal of time on repetitive tasks, such as cataloging best-sellers, while ignoring the most valuable aspects of their collections: the archives, the rare items, the unique collections. The report urged libraries to "transfer effort into higher value activity" and separately called for libraries to embrace the web as the primary technology infrastructure.The web scale library management system should provide the tools for libraries to do this higher value work, including synthesizing and specializing resources for a local environment.
Furthermore, rather than competing with other library sector technology vendors, OCLC should build the infrastructure that allows those vendors to build services on top of the WorldCat platform in the same way that Flickr works with partner companies who add value to their services. I know this is a tricky process, but it probably starts with open APIs.
Friday, November 14, 2008
finding full text with Google Scholar
The Google Operating System Blog had a post the other day that alerted me to a relatively new feature in Google Scholar. For each article in a result set, Google Scholar will point you to a free, unrestricted copy of the article on the web (if available) with a little green ►.
With many academic journal publishers allowing authors to post copies of their articles on their personal websites, it is now common for scholarly articles in subscription journals to be available for free on the open web. Below is an example of an article, with a copy available from a website in an academic domain (sorry for the tiny image).
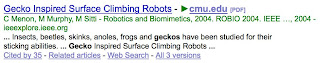
This is a good example of Google Scholar leveraging the Google web index to provide something you can't get within the research systems that libraries have built and licensed. It's also yet another reminder that libraries and publishers have lost their role as sole provider and intermediary for academic content.
I've pointed out previously in this blog that creators of research products for libraries do not (or are not able) to take advantage of web indexes as they create their products. I wonder if openurl resolver vendors or someone like OCLC could offer this feature by tapping into something like the Alexa Web Search service to mine the web for full copies of a given article? It might be hard to do on the fly with a resolver request.
I'm guessing that Google Scholar will have 90%+ of scholarly articles in existence in its index at the citation level in the not-to-distant future. It is able to mine so many places for citations: web sites, scanned books and journals, and many publishers' archives, etc.
As OCLC loads article citations into Open WorldCat, I wonder if they have considered a more "brute force" approach to finding citations. They could mine the web for them like Google. Of course, this would introduce all sorts of possibilities for errors and lack of bibliographic control. Google Scholar must have lots of errors in the citations it collects, but it seems to efficiently collate like citations together and recognize which citations are the most referenced.
With many academic journal publishers allowing authors to post copies of their articles on their personal websites, it is now common for scholarly articles in subscription journals to be available for free on the open web. Below is an example of an article, with a copy available from a website in an academic domain (sorry for the tiny image).

This is a good example of Google Scholar leveraging the Google web index to provide something you can't get within the research systems that libraries have built and licensed. It's also yet another reminder that libraries and publishers have lost their role as sole provider and intermediary for academic content.
I've pointed out previously in this blog that creators of research products for libraries do not (or are not able) to take advantage of web indexes as they create their products. I wonder if openurl resolver vendors or someone like OCLC could offer this feature by tapping into something like the Alexa Web Search service to mine the web for full copies of a given article? It might be hard to do on the fly with a resolver request.
I'm guessing that Google Scholar will have 90%+ of scholarly articles in existence in its index at the citation level in the not-to-distant future. It is able to mine so many places for citations: web sites, scanned books and journals, and many publishers' archives, etc.
As OCLC loads article citations into Open WorldCat, I wonder if they have considered a more "brute force" approach to finding citations. They could mine the web for them like Google. Of course, this would introduce all sorts of possibilities for errors and lack of bibliographic control. Google Scholar must have lots of errors in the citations it collects, but it seems to efficiently collate like citations together and recognize which citations are the most referenced.
Tuesday, August 19, 2008
del.icio.us project linking to WorldCat.org
I just heard that the collection of site-based research resources that our Environmental Studies program has created using del.icio.us (see previous post) is linking into WorldCat.org whenever it references a book or article (when the article citation is included in WorldCat). Many of these references are examples.
In some previous iterations of this project, they had been linking to references for books and articles in RefWorks. But such a reference isn't as useful for someone who finds this reference from outside our institution. WorldCat.org provides a nice authoritative reference point for academic resources because it provides the means to acquire the resource through your own library. Amazon often fulfills this role for books, but its nice to see WorldCat step into the picture.
I'm assuming that when Summit goes live on WorldCat Navigator, it will be easy to move from a record in WorldCat.org to that delivery system.
I know that WorldCat.org has loaded lots of journal articles recently. The more, the better! Someday, perhaps, it will be an "authoritative" location for journal article citations.
Wednesday, April 25, 2007
Freebase explored
Got a chance to try out Freebase thanks to an account from Paul Miller.
Once you've logged in, the site has some nice Flash based tutorials that explain the idea behind the service pretty well. You can also browse the categories 'types' that are setup in freebase. Basically, they are designed to span the world's knowledge, a pretty ambitious goal. Top level types include:
The amount of data in these areas is still pretty small. They've pre-loaded data about films and restaurants; many of the demo applications take advantage of this data, such as cinespinner.
As I browsed through the categories, I thought about how similar this kind of organization is to library cataloging, especially authority control. It would be great if the catalog and authority data in WorldCat was pre-loaded into Freebase, as well as other datasets with a certain amount of authority such as the Getty Vocabulary Program. Seems like it would also make sense to massively load in data about consumer products.
How to convince organizations to put their data into this open database? Perhaps they could get a fee based on queries using their data when a Freebase account went over a certain daily query limit. Sort of an Amazon web services model. I guess that would make it unfree, technically, but what really is?
Thinking more broadly, once the rules were established for a global database of knowledge, it could be replicated and hosted by more than one organization--with each hosting company providing basic querying functionality but also perhaps some value added services. Those are my anti-monopolistic tendencies showing through.
Once you've logged in, the site has some nice Flash based tutorials that explain the idea behind the service pretty well. You can also browse the categories 'types' that are setup in freebase. Basically, they are designed to span the world's knowledge, a pretty ambitious goal. Top level types include:
- media
- sports
- science and technology
- art
- travel and dining
- special interests
The amount of data in these areas is still pretty small. They've pre-loaded data about films and restaurants; many of the demo applications take advantage of this data, such as cinespinner.
As I browsed through the categories, I thought about how similar this kind of organization is to library cataloging, especially authority control. It would be great if the catalog and authority data in WorldCat was pre-loaded into Freebase, as well as other datasets with a certain amount of authority such as the Getty Vocabulary Program. Seems like it would also make sense to massively load in data about consumer products.
How to convince organizations to put their data into this open database? Perhaps they could get a fee based on queries using their data when a Freebase account went over a certain daily query limit. Sort of an Amazon web services model. I guess that would make it unfree, technically, but what really is?
Thinking more broadly, once the rules were established for a global database of knowledge, it could be replicated and hosted by more than one organization--with each hosting company providing basic querying functionality but also perhaps some value added services. Those are my anti-monopolistic tendencies showing through.
Subscribe to:
Posts (Atom)