One of our biggest frustrations with WorldCat Local has been the difficulties involved in surfacing e-book collections. The standard way of adding an ebook set to your catalog--uploading a file of MARC records provided by the vendor--doesn't surface records in WCL.
To get records for an e book set in WCL, you need to add records to your local ILS catalog, make sure those records have OCLC numbers in them and have your holdings set on the corresponding records in OCLC. This can be hard to achieve if vendor provided record sets don't have OCLC numbers on them to start with.
OCLC has an initiative in place to get vendor supplied MARC records into WorldCat, but agreements are not in place for all vendors and the process is somewhat cumbersome. Also, as I understand it, in some cases these vendor record sets aren't truly in WorldCat, they just show up in certain WorldCat Local instances where the library subscribes to the ebook collection. Effectively, this is creating "shadow" records in WorldCat that are only available to certain subscribers.
I really wish that we could just flip on and off collections of ebooks in WCL in the same way that one adds and removes collections of e journals in Serials Solutions' management interface. Having to load records into a local system and worry about connecting those records to OCLC records is a big hassle. I realize that there may be some vendor licensing issues that prevent this, but this seems like a good goal.
Perhaps there could be some kind of connection between Serials Solutions and OCLC along the same lines as their e serials holdings project that would achieve this sort of ease in adding and removing e book sets.
Another question to ask within the e book arena: why are we so dependent on vendors for bibliographic records? Libraries should be able to collectively catalog e book sets, especially in cases where the vendors want to hold their records tightly to their chest. Some kind of crowdsourcing application for cataloging an entire e book set might achieve this. Any libraries who want records for a certain e book set sign up, and the app divvies up cataloging between them.
Showing posts with label WorldCat Local. Show all posts
Showing posts with label WorldCat Local. Show all posts
Tuesday, February 16, 2010

Wednesday, September 23, 2009
Summon 'web scale'? I don't think so.
I think it's strange that Serials Solutions is attempting to apply the "web-scale" adjective to their Summon Service.
As far as I can tell, the library community has really co-opted this term from its original use, which pertained to computing infrastructure that could support web sites that handle huge amounts of traffic. Perhaps Lorcan Dempsey widened the use of the term in January 2007:
I attended a webinar on Summon yesterday, and found out that with Summon, Serials Solutions creates a broad index of content available to your library: books, journals, digital collections, etc. It gets the data from your library uploading data and from the e content vendors with which your library has relations. The data goes in a SOLR index, which then can serve as a comprehensive discovery tool for your library's content. Because it is built on local data and tailored for a particular user community this sounds much more like an 'intranet' type search than anything that is "web scale."
WorldCat Local with its upcoming metasearch features does something similar, but I think that it can make a more legitimate claim to the "web scale" designation because it is attached to the WorldCat.org database. In my opinion, WorldCat.org is web scale in the sense that it is used and improved by a global community.
Summon and WorldCat Local are competing in the same discovery interface space. On first glance, it appears that Serials Solutions is ahead of OCLC in the incorporation of article content, perhaps because of their close relations with content vendors. OCLC seems to have the edge in books: they are able to leverage holdings data in relevance rankings and they have a more sophisticated treatment of various editions of the same work (FRBR). OCLC is also endeavoring to provide delivery services in addition to discovery.
It will be interesting to see if OCLC can use its global database and the Web 2.0 principle "it gets better the more people use it" to differentiate its product from competitors like Summon.
I don't think its obvious, but what OCLC is trying to do with WorldCat is much bolder than Serials Solutions and Summon. With Summon, libraries are basically throwing all of their content into one index to break down the data silos within an institution. But what you end up with is a big search silo for that institution.
With WorldCat, the vision is to break down not only the silos within institutions but also the silos between institutions. And not just break down those silos in the sense of harvest-and-search. The concept is that libraries and their patrons will be working together to improve a shared database through intentional and professional metadata. This shared database will be big enough to have a real impact on the web. Its records will surface in search engine results. Its interface will be familiar to many, and it will be customizable for a particular audience via the WorldCat Local route.
We'll see if this grand vision takes hold.
As far as I can tell, the library community has really co-opted this term from its original use, which pertained to computing infrastructure that could support web sites that handle huge amounts of traffic. Perhaps Lorcan Dempsey widened the use of the term in January 2007:
'Web-scale' refers to how major web presences architect systems and services to scale as use grows. But it also seems evocative in a broader way of the general attributes of the large gravitational hubs which are such a feature of the current web (eBay, Amazon, Google, WikiPedia, ...).This reference to 'web scale' is now at the top of Google results for the term, making me think that the library community has just about taken over the term.
I attended a webinar on Summon yesterday, and found out that with Summon, Serials Solutions creates a broad index of content available to your library: books, journals, digital collections, etc. It gets the data from your library uploading data and from the e content vendors with which your library has relations. The data goes in a SOLR index, which then can serve as a comprehensive discovery tool for your library's content. Because it is built on local data and tailored for a particular user community this sounds much more like an 'intranet' type search than anything that is "web scale."
WorldCat Local with its upcoming metasearch features does something similar, but I think that it can make a more legitimate claim to the "web scale" designation because it is attached to the WorldCat.org database. In my opinion, WorldCat.org is web scale in the sense that it is used and improved by a global community.
Summon and WorldCat Local are competing in the same discovery interface space. On first glance, it appears that Serials Solutions is ahead of OCLC in the incorporation of article content, perhaps because of their close relations with content vendors. OCLC seems to have the edge in books: they are able to leverage holdings data in relevance rankings and they have a more sophisticated treatment of various editions of the same work (FRBR). OCLC is also endeavoring to provide delivery services in addition to discovery.
It will be interesting to see if OCLC can use its global database and the Web 2.0 principle "it gets better the more people use it" to differentiate its product from competitors like Summon.
I don't think its obvious, but what OCLC is trying to do with WorldCat is much bolder than Serials Solutions and Summon. With Summon, libraries are basically throwing all of their content into one index to break down the data silos within an institution. But what you end up with is a big search silo for that institution.
With WorldCat, the vision is to break down not only the silos within institutions but also the silos between institutions. And not just break down those silos in the sense of harvest-and-search. The concept is that libraries and their patrons will be working together to improve a shared database through intentional and professional metadata. This shared database will be big enough to have a real impact on the web. Its records will surface in search engine results. Its interface will be familiar to many, and it will be customizable for a particular audience via the WorldCat Local route.
We'll see if this grand vision takes hold.
Wednesday, September 9, 2009
WorldCat Local Review
I've written a fair amount in the abstract about the benefits of WorldCat.org and WorldCat Local.
At Watzek, we launched "L&C WorldCat" around July 1. Here are some thoughts based on my experience with the implementation.
At Watzek, we launched "L&C WorldCat" around July 1. Here are some thoughts based on my experience with the implementation.
- There is already a sense developing at our school that "everything" is in or should be in WorldCat Local. People expect all articles and books to be there (even though they aren't). I may post more on this later.
- Compared with launching an III OPAC, the process of bringing WCL up is refreshingly simple. They have consciously limited customization to the very basics (logo, colors, etc.)
- Even so, as I've said before in this blog, I'd prefer a greater level of customize-abilty, kind of on the level of Blogger. Give me full access to the stylesheet. Let me add code snippets.
- It's backward that the software pulls in live holdings data for print items from your ILS, but can't pull in links to digital content from your link resolver. When students come upon an article, they want the direct link to it up front, not a click or two away. OCLC should scrape resolvers like they do ILSs to embed link resolver links in records for articles.
- I'm excited about the idea of OCLC partnering with content providers like EBSCO and indexing their content in WC. One thing I speculated on when writing the Digital Libraries book in '06 was that following on the success of search engines, meta indexing services for library content would eventually emerge. We now see that with Serials Solutions Summon and WorldCat.
- The idea of also incorporating in traditional real-time meta-searching seems like a backward compromise: OCLC should be firm with content providers and resolve to only incorporate content that they can put into their index.
- The stats module for WCL is basically a commercial web analytics package slapped onto WCL with a few limited custom reports. Basically, you can look at your site traffic and search terms being used.
- I like the idea of using standard web analytics software on WCL, but please let me drop the code snippet in for Google Analytics.
- If they did some url rewriting so as to map some of the search/browsing activity to clean URL paths (eg "/author/" "/title/" "/facet/video/") web analytics software becomes more useful because you can collate together like activities based on url paths.
- For a minute, I was thinking that to provide access to an e book package we purchased through WCL, all we'd need to do is "flip the switch" and activate our holdings for those records in WCL, forget about ILS records. But then I remembered: the URLs to that package need to go through our proxy server so they need to be drawn from our ILS. WCL is not making our lives easier yet.
- A little off the subject, but now that OCLC owns EZproxy, aren't they in a great position to develop some better, more graceful form of remote authentication than proxy? OCLC could act as a trusted third party and provide single sign on to content provider websites.
Tuesday, March 24, 2009
thinking more about OneBoxing WorldCat Local

I just checked with our implementation guy at OCLC about including some code in the header of our WorldCat Local instance that would allow us to add customized widgets into WorldCat Local search result screens. Sounds like it's a no go for now. WorldCat Local has a refreshingly simple branding customization options compared to what we're used to with Innovative's OPAC. But that simplicity will keep us from inserting some magic Javascript to achieve the OneBox effect.
I'm not sure if I was clear enough about what I'm interested in. Another way of looking at this is analagous to Google Ads. Google has established that placing context sensitive ads alongside search engine results is an effective way to drive traffic to advertiser websites.
If WorldCat Local becomes our library's search engine, shouldn't our library be able to put context sensitive "ads" next to results? These "ads" (or OneBoxes) would appear based on the search term and offer things like:
- links to library created research guides that seem relevant to search at hand
- links to course reserves if a prof's name is searched
- results from a site search of our library's site
- image results from ARTstor (ala Google images)
- results (if any) from the library's digital collections
The WorldCat API is nice and all, but who (besides Terry Reese) wants to build an entire interface from scratch using it?
Click on the image above for an illustration of the WorldCat Local OneBox concept.
Tuesday, March 17, 2009
OneBoxes for WorldCat Local
In thinking through the options for placing the searchbox for WorldCat Local on our website, I'm inclined to argue for a single search box on the homepage rather than the somewhat confusing tabbed box that we have now. After all, WCL should get us to our "catalog" content, journal titles, and provide a general article search.

The problem with offering a single search box to patrons is that we miss content that they might want from a library site search: links to research database, course reserves, library hours, librarian contact info, etc.
WorldCat Local might be improved if it had the option to integrate Google style "OneBoxes" in its results display. A little box off to the side might highlight items like course reserves or matches from a site search.
I have a feeling, I'll probably lose the argument regarding a single search box on our website. After all, even Google offers users multiple silos of content to search (Books, Web, Blogs, News, etc.).

The problem with offering a single search box to patrons is that we miss content that they might want from a library site search: links to research database, course reserves, library hours, librarian contact info, etc.
WorldCat Local might be improved if it had the option to integrate Google style "OneBoxes" in its results display. A little box off to the side might highlight items like course reserves or matches from a site search.
I have a feeling, I'll probably lose the argument regarding a single search box on our website. After all, even Google offers users multiple silos of content to search (Books, Web, Blogs, News, etc.).
Friday, November 14, 2008
finding full text with Google Scholar
The Google Operating System Blog had a post the other day that alerted me to a relatively new feature in Google Scholar. For each article in a result set, Google Scholar will point you to a free, unrestricted copy of the article on the web (if available) with a little green ►.
With many academic journal publishers allowing authors to post copies of their articles on their personal websites, it is now common for scholarly articles in subscription journals to be available for free on the open web. Below is an example of an article, with a copy available from a website in an academic domain (sorry for the tiny image).
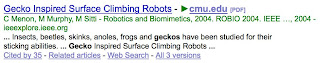
This is a good example of Google Scholar leveraging the Google web index to provide something you can't get within the research systems that libraries have built and licensed. It's also yet another reminder that libraries and publishers have lost their role as sole provider and intermediary for academic content.
I've pointed out previously in this blog that creators of research products for libraries do not (or are not able) to take advantage of web indexes as they create their products. I wonder if openurl resolver vendors or someone like OCLC could offer this feature by tapping into something like the Alexa Web Search service to mine the web for full copies of a given article? It might be hard to do on the fly with a resolver request.
I'm guessing that Google Scholar will have 90%+ of scholarly articles in existence in its index at the citation level in the not-to-distant future. It is able to mine so many places for citations: web sites, scanned books and journals, and many publishers' archives, etc.
As OCLC loads article citations into Open WorldCat, I wonder if they have considered a more "brute force" approach to finding citations. They could mine the web for them like Google. Of course, this would introduce all sorts of possibilities for errors and lack of bibliographic control. Google Scholar must have lots of errors in the citations it collects, but it seems to efficiently collate like citations together and recognize which citations are the most referenced.
With many academic journal publishers allowing authors to post copies of their articles on their personal websites, it is now common for scholarly articles in subscription journals to be available for free on the open web. Below is an example of an article, with a copy available from a website in an academic domain (sorry for the tiny image).

This is a good example of Google Scholar leveraging the Google web index to provide something you can't get within the research systems that libraries have built and licensed. It's also yet another reminder that libraries and publishers have lost their role as sole provider and intermediary for academic content.
I've pointed out previously in this blog that creators of research products for libraries do not (or are not able) to take advantage of web indexes as they create their products. I wonder if openurl resolver vendors or someone like OCLC could offer this feature by tapping into something like the Alexa Web Search service to mine the web for full copies of a given article? It might be hard to do on the fly with a resolver request.
I'm guessing that Google Scholar will have 90%+ of scholarly articles in existence in its index at the citation level in the not-to-distant future. It is able to mine so many places for citations: web sites, scanned books and journals, and many publishers' archives, etc.
As OCLC loads article citations into Open WorldCat, I wonder if they have considered a more "brute force" approach to finding citations. They could mine the web for them like Google. Of course, this would introduce all sorts of possibilities for errors and lack of bibliographic control. Google Scholar must have lots of errors in the citations it collects, but it seems to efficiently collate like citations together and recognize which citations are the most referenced.
thinking locally, acting globally
As our library discusses moving to WorldCat Local as our "primary" library catalog, the catalogers have been voicing their concerns about relying on the master records in the WorldCat database for our local catalog. They are very concerned that the corrections and augmentations that they apply to our local bibliographic records will no longer be visible. These often take the form of local subject headings, genre headings, corrections, etc. The logical move of course is to make those changes in the WorldCat database where they can have a global benefit.
The move to WorldCat as the live local database should force the issue of truly cooperative cataloging, and I think that's a good thing. It should give incentive to OCLC to be more inclusive about who can edit and enhance records and it should embolden catalogers to work in the global catalog, not just their local one.
In the networked environment we're doing more and more work in libraries that benefits a global community, rather than just our local community. Digital collections projects are a good example. When we digitize unique art, photos, manuscripts, or historical documents, our work provides value to the world. These collections are contributing to the de facto world digital library that is the Internet. Our print collections, especially the more unique pieces within them, are also making a more global contribution as ILL systems become better lubricated.
How do this work benefit the parent institutions that fund us? Should we only be doing projects with a global benefit if they provide a benefit to our institutions equal to their cost? In some ways this seems logical: we take action when there is a clear local benefit and view any global benefit as a positive side effect. Sort of akin to a "national interest" foreign policy doctrine.
I think about this as I spend time working on accessceramics.org. It's very satisfying to be developing a resource for a global audience rather than just our local one. We can see the visitors coming in from around the world on Google Analytics. But our library like most any academic library is structured and funded as an organization that provides a wide set of rather generic services to a very defined audience. We're not really optimized for developing a narrow, niche collection that we serve up to the world. The Internet has taken away many of the barriers for doing this, however, and we are starting to forge ahead with collections like these.
In some ways, the model for academic libraries doing niche collections is like humanities scholarship, where the revenue from teaching subsidizes research. The services a library provides to a primary audience of students and faculty are akin to the teaching and the niche collections with a global benefit are equivalent to the research. In the same way that an academic's research benefits their teaching (or does it?), does a library's curation of niche collections make the library better in the primary services that it provides to its patrons: reference, instruction, discovery to delivery, etc.?
The local benefit of a digital project can obviously hard to measure, but clearly some unique collections have particular relevance and value to a community. Historical documents that support a niche area of scholarship that is a strength of the institution, a photo collection about the surrounding community, etc. accessCeramics supports a strong tradition of ceramic arts instruction at our institution.
Many niche projects raise the profile of the parent institution broadly and have the potential to boost funds coming in from grants and donors. Libraries tend to take pride, rightfully, in the work they do that has global benefit and, indeed, most wish they had more staff resources to undertake such projects.
The move to WorldCat as the live local database should force the issue of truly cooperative cataloging, and I think that's a good thing. It should give incentive to OCLC to be more inclusive about who can edit and enhance records and it should embolden catalogers to work in the global catalog, not just their local one.
In the networked environment we're doing more and more work in libraries that benefits a global community, rather than just our local community. Digital collections projects are a good example. When we digitize unique art, photos, manuscripts, or historical documents, our work provides value to the world. These collections are contributing to the de facto world digital library that is the Internet. Our print collections, especially the more unique pieces within them, are also making a more global contribution as ILL systems become better lubricated.
How do this work benefit the parent institutions that fund us? Should we only be doing projects with a global benefit if they provide a benefit to our institutions equal to their cost? In some ways this seems logical: we take action when there is a clear local benefit and view any global benefit as a positive side effect. Sort of akin to a "national interest" foreign policy doctrine.
I think about this as I spend time working on accessceramics.org. It's very satisfying to be developing a resource for a global audience rather than just our local one. We can see the visitors coming in from around the world on Google Analytics. But our library like most any academic library is structured and funded as an organization that provides a wide set of rather generic services to a very defined audience. We're not really optimized for developing a narrow, niche collection that we serve up to the world. The Internet has taken away many of the barriers for doing this, however, and we are starting to forge ahead with collections like these.
In some ways, the model for academic libraries doing niche collections is like humanities scholarship, where the revenue from teaching subsidizes research. The services a library provides to a primary audience of students and faculty are akin to the teaching and the niche collections with a global benefit are equivalent to the research. In the same way that an academic's research benefits their teaching (or does it?), does a library's curation of niche collections make the library better in the primary services that it provides to its patrons: reference, instruction, discovery to delivery, etc.?
The local benefit of a digital project can obviously hard to measure, but clearly some unique collections have particular relevance and value to a community. Historical documents that support a niche area of scholarship that is a strength of the institution, a photo collection about the surrounding community, etc. accessCeramics supports a strong tradition of ceramic arts instruction at our institution.
Many niche projects raise the profile of the parent institution broadly and have the potential to boost funds coming in from grants and donors. Libraries tend to take pride, rightfully, in the work they do that has global benefit and, indeed, most wish they had more staff resources to undertake such projects.
Friday, October 10, 2008
system migration therapy
I just came across this advice in an email from Kyle Banerjee regarding the upcoming Summit Migration to WorldCat Navigator:
The stages of migrationI wonder if Kyle offers therapy sessions for working through these stages? Seriously, though, I think he speaks the truth.
Having been through a few major systems migrations, I think that you'll find this process easier if you're aware of certain stages people naturally go through.
The first stage consists of unfavorable comparisons of the new system to the old system. INN-Reach is good at what it does. People know its strengths and know how to get the most of it. Especially in the beginning, staff will naturally think about Nav the way they do about INN-Reach. Since Nav doesn't do some things the same and its strengths will be different, staff will quickly discover weaknesses while not being able to capitalize on the strengths. Some staff may use the system in a way that magnifies these differences. This stage is typically accompanied by nostalgic sentiments towards the old system, negative feelings for the new system, and a high level of stress.
In the second stage, people start getting used to the system. They learn how to do what they need, discover a few neat tricks, and develop workarounds for the weaknesses discovered in the first stage. During this time, people settle into a groove and things operate smoothly. Feelings towards the new and old system become more balanced as people perceive them as the different beasts that they are.
In the third stage, people figure out what the new system does best and reconfigure their workflows to maximize the system's strengths while minimizing the impact of its weaknesses. By this time, people see the migration as a positive event, and many can hardly believe the things they used to do.
Most of you have undoubtedly been through at least one migration and probably recognize the stages listed above. My point is that if you feel stressed at the beginning, it's important to recognize this is a natural part of the process. Things won't just get better -- soon enough they'll be better than they've ever been.
Monday, April 14, 2008
OCLC's competitive advantage
In a previous post, I mentioned the "cloud computing" aspects of the WorldCat.org platform when used in the form of WorldCat Local or WorldCat Group to replace an ILS based catalog. A couple weeks ago, I got some more thoughts together on this, but some other distractions pulled me away.
Last year, as part of my work with the Orbis Cascade Alliance's Catalog Committee, I got to survey the market for next generation library catalogs/discovery systems. In my mind, OCLC's WorldCat Group/Local option stands out against both the open source and commercial competition. Why? Because of network effects.
Competitors making products like ExLibris's Primo and Innovative Interface's Encore simply don't have access to the data that OCLC does, and neither does the open source community. OCLC's holdings data lets them do relevance ranking by the number of libraries that own the item. Its global database allows the potential of expanding a search beyond a single library or group of libraries to a global database with built-in ILL. WorldCat offers records that are updated and improved over time by shared cataloging, and the possiblity of enrichment of those records by web-scale social networking (reviews, tags, etc.). WorldCat is a living organism that can't simply be replicated on someone else's server.
These advantages are byproducts of the cataloging and resource sharing networks that OCLC has had in place for years. They are more about a community committed to sharing resources than about technology.
It's also about exclusive access to data, which fits in nicely with Tim O'Reilly's Web 2.0 tenant, data is the next Intel Inside.
Another way to think about this is that OCLC is in a position to be a sort of EBay for libraries. EBay is valuable precisely because of its wide user base. It is the dominant player in online auctions because it offers the widest possible marketplace for buyers and sellers. That same comprehensiveness and global scope also has value when building a search system for books and doing resource sharing.
Traditional ILS vendors have little tradition of sharing data between their customers. I really can't imagine Innovative Interfaces putting together any kind of product that involves mixing customers data (that weren't part of a consortium doing direct business with them). The whole idea of mixing customer data seems like it would run counter to traditional notions of enterprise level systems, and would really be hard for a longstanding software company to grasp (though I have to point out that Talis is very much an exception). Most customers buying enterprise software wouldn't want to share their data with peers anyway, right?
But that is really a non-issue for libraries, and precisely what this Web 2.0 world calls for, and what OCLC has been doing for a long time. OCLC has this valuable data, and great potential to develop things with it, as well as a general current towards network-level computing moving in its favor. When libraries compare OCLC's products with that of a traditional ILS vendor, they need to see that the OCLC product is more than technology. Rather, it is an extension of a community, a network. The commercial vendors just can't offer that.
OCLC doesn't really have a monopoly on bibliographic data. But they definitely are one of the largest players out there, and their data could put them way out ahead. They are in a position to create an impressive platform with their WorldCat.org line of products. As they do this, they should build it so that it's open enough that other companies and organizations can build products on top of it.
The model I'm thinking of is Flickr. Flickr is a great global platform for photo sharing, but through their API, Yahoo also lets other firms get in there and add value to it. OCLC should be build WorldCat as an information ecosystem that allows the library community to have a healthy marketplace of technology products. (They sort of have this model going with ILL, but there aren't too many competitors out there to OCLC's ILL management product, ILLIAD.) OCLC's new APIs for WorldCat are a sign that they are moving in this direction.
OCLC's competitive advantage in holdings data and shared cataloging applies largely to print materials. They really don't have any such advantage in the realm of electronic information: e journals, digital collections, etc.. They might be going after this with acquisition of companies like Openly Informatics and the ContentDM software, but even so, they are not in possession of data that gives them a competitive advantage in the same way as their cataloging and resource sharing networks. Many companies like ExLibris and Serials Solutions have e-serials holdings data. And data about library digital collections is generally open for harvesting/crawling.
Even in print material, Google Books could be a viable competitor to OCLC in the library search arena, especially because they have the advantage of full text searching. They have lots of data that OCLC doesn't. It would even be possible now with the Google AJAX search API to create a Google Book Search that linked back to your library catalog for books held in your library.
Last year, as part of my work with the Orbis Cascade Alliance's Catalog Committee, I got to survey the market for next generation library catalogs/discovery systems. In my mind, OCLC's WorldCat Group/Local option stands out against both the open source and commercial competition. Why? Because of network effects.
Competitors making products like ExLibris's Primo and Innovative Interface's Encore simply don't have access to the data that OCLC does, and neither does the open source community. OCLC's holdings data lets them do relevance ranking by the number of libraries that own the item. Its global database allows the potential of expanding a search beyond a single library or group of libraries to a global database with built-in ILL. WorldCat offers records that are updated and improved over time by shared cataloging, and the possiblity of enrichment of those records by web-scale social networking (reviews, tags, etc.). WorldCat is a living organism that can't simply be replicated on someone else's server.
These advantages are byproducts of the cataloging and resource sharing networks that OCLC has had in place for years. They are more about a community committed to sharing resources than about technology.
It's also about exclusive access to data, which fits in nicely with Tim O'Reilly's Web 2.0 tenant, data is the next Intel Inside.
Another way to think about this is that OCLC is in a position to be a sort of EBay for libraries. EBay is valuable precisely because of its wide user base. It is the dominant player in online auctions because it offers the widest possible marketplace for buyers and sellers. That same comprehensiveness and global scope also has value when building a search system for books and doing resource sharing.
Traditional ILS vendors have little tradition of sharing data between their customers. I really can't imagine Innovative Interfaces putting together any kind of product that involves mixing customers data (that weren't part of a consortium doing direct business with them). The whole idea of mixing customer data seems like it would run counter to traditional notions of enterprise level systems, and would really be hard for a longstanding software company to grasp (though I have to point out that Talis is very much an exception). Most customers buying enterprise software wouldn't want to share their data with peers anyway, right?
But that is really a non-issue for libraries, and precisely what this Web 2.0 world calls for, and what OCLC has been doing for a long time. OCLC has this valuable data, and great potential to develop things with it, as well as a general current towards network-level computing moving in its favor. When libraries compare OCLC's products with that of a traditional ILS vendor, they need to see that the OCLC product is more than technology. Rather, it is an extension of a community, a network. The commercial vendors just can't offer that.
OCLC doesn't really have a monopoly on bibliographic data. But they definitely are one of the largest players out there, and their data could put them way out ahead. They are in a position to create an impressive platform with their WorldCat.org line of products. As they do this, they should build it so that it's open enough that other companies and organizations can build products on top of it.
The model I'm thinking of is Flickr. Flickr is a great global platform for photo sharing, but through their API, Yahoo also lets other firms get in there and add value to it. OCLC should be build WorldCat as an information ecosystem that allows the library community to have a healthy marketplace of technology products. (They sort of have this model going with ILL, but there aren't too many competitors out there to OCLC's ILL management product, ILLIAD.) OCLC's new APIs for WorldCat are a sign that they are moving in this direction.
OCLC's competitive advantage in holdings data and shared cataloging applies largely to print materials. They really don't have any such advantage in the realm of electronic information: e journals, digital collections, etc.. They might be going after this with acquisition of companies like Openly Informatics and the ContentDM software, but even so, they are not in possession of data that gives them a competitive advantage in the same way as their cataloging and resource sharing networks. Many companies like ExLibris and Serials Solutions have e-serials holdings data. And data about library digital collections is generally open for harvesting/crawling.
Even in print material, Google Books could be a viable competitor to OCLC in the library search arena, especially because they have the advantage of full text searching. They have lots of data that OCLC doesn't. It would even be possible now with the Google AJAX search API to create a Google Book Search that linked back to your library catalog for books held in your library.
Tuesday, March 25, 2008
bibliographic utility computing
As OCLC re-invents itself from a staid bibliographic utility to a company that can provide "next generation" library services, it's funny how that old fashioned term "utility" takes on a new meaning.
I was at the Orbis Cascade Alliance Council meeting last week as the group was discussing the possiblity of a partnership with OCLC for a group catalog on the WorldCat.org platform. As I reflected on the consortium's potential move from an isolated, server based union catalog, to one that lives in the cloud I thought about how this decision parallels those that many organizations will be making in the next few years as they make what Nick Carr has dubbed, The Big Switch to utility style computing. OCLC likes to call this "moving to the network level," but I think it's also just as much a move to "cloud" or utility style computing.
I'd heard most of what the OCLC sales force had to say at the meeting before. But one thing that struck me was how they explained the point of worldcat.org. OCLC believes that libraries need a "presence" on the web like EBay, Amazon, or Google. And that presence needs to be two-way, meaning users interact with the site and their interaction improves it.
If WorldCat is able to become a real "presence", maybe more database vendors will be open to representing their content in it and it will become a federated search killer. Maybe libraries can have more control over the digital content they give their users vs. just sending them off to an external, commercial website.
Where does local customization and control play in this potential juggernaut? Hopefully OCLC will keep opening up their APIs, and let libraries still have the ability to customize their own records in various ways.
I was at the Orbis Cascade Alliance Council meeting last week as the group was discussing the possiblity of a partnership with OCLC for a group catalog on the WorldCat.org platform. As I reflected on the consortium's potential move from an isolated, server based union catalog, to one that lives in the cloud I thought about how this decision parallels those that many organizations will be making in the next few years as they make what Nick Carr has dubbed, The Big Switch to utility style computing. OCLC likes to call this "moving to the network level," but I think it's also just as much a move to "cloud" or utility style computing.
I'd heard most of what the OCLC sales force had to say at the meeting before. But one thing that struck me was how they explained the point of worldcat.org. OCLC believes that libraries need a "presence" on the web like EBay, Amazon, or Google. And that presence needs to be two-way, meaning users interact with the site and their interaction improves it.
If WorldCat is able to become a real "presence", maybe more database vendors will be open to representing their content in it and it will become a federated search killer. Maybe libraries can have more control over the digital content they give their users vs. just sending them off to an external, commercial website.
Where does local customization and control play in this potential juggernaut? Hopefully OCLC will keep opening up their APIs, and let libraries still have the ability to customize their own records in various ways.
Tuesday, November 20, 2007
OCLC and network level services
OCLC is loading up on the big names in the digital library world. Of course, they've had Lorcan Dempsey for awhile. They recently picked up Roy Tennant and most recently, they hired Andrew Pace as Executive Director of Network Level Services. That job title makes me think that Dempsey had something to do with designing the job. An old OCLC hand out here in the Pacific Northwest recently referred to him as "Lorcan our prophet." Apparently he really does have a hand at shaping company strategy.
I know Andrew Pace some from the '06 Frye institute and offer my congratulations to him. I always used to see his columns in Computers in Libraries and think he was just another dork writing about library technology. At Frye, I discovered that he's a pretty enjoyable and interesting guy to listen to and in person is always dropping this funny, sometimes southern flavored aphorisms when describing various dilemmas and situations in the library world. I guess "lipstick on a pig" might be an example. I think he'll do a bang up job in this new position. As much as he's a thinker and observer, I know he's also a doer, as the NCSU catalog demonstrates.
In my humble opinion, OCLC has a lot of work to do on their "network-level" services. Here's a few areas where they could stand to improve:
I know Andrew Pace some from the '06 Frye institute and offer my congratulations to him. I always used to see his columns in Computers in Libraries and think he was just another dork writing about library technology. At Frye, I discovered that he's a pretty enjoyable and interesting guy to listen to and in person is always dropping this funny, sometimes southern flavored aphorisms when describing various dilemmas and situations in the library world. I guess "lipstick on a pig" might be an example. I think he'll do a bang up job in this new position. As much as he's a thinker and observer, I know he's also a doer, as the NCSU catalog demonstrates.
In my humble opinion, OCLC has a lot of work to do on their "network-level" services. Here's a few areas where they could stand to improve:
- ILL: the current mish-mash of products for managing interlibrary loan is pretty lame and is a real time sucker for library systems people. In most situations, these include an ILL management system (Clio/Illiad) for workflow management and patron interaction, a system for sending and receiving documents (Ariel), and the OCLC resource sharing network. There's no reason that OCLC shouldn't be able to provide a comprehensive ILL management suite including document exchange, workflow, and patron interaction as an entirely web-based, hosted tool, and offer it as a basic part of their ILL service.
- Digital collections software: ContentDM is a relic from the 1990s. It's a strange hodgepodge of C code and PHP, is clunky as hell, not to mention that it produces the ugliest looking URLs and no page titles, making it terrible for search engine crawling. Someone good at Ruby on Rails could build a better piece of software in a weekend. (Perhaps I'm just a little annoyed with it right now because I've been working on getting a Google Search Appliance to index our ContentDM collections) OCLC should be offering a fully hosted, web scale digital asset management system with web-based client software on par with somthing like Flickr. They could offer migration from ContentDM
- Semantic web strategy: OCLC needs to follow the Talis into the semantic web space. They need to be designing systems that share data in an open fashion.
- WorldCat Local: This is where OCLC has got it most right recently, in my opinion. If they add an API, and make the UI more customizable, and allow for localized versions of records, they'll be in business.
- Partnerships with large-scale players: OCLC is positions to make partnerships with big players in the information space like Google. They've found ways to bring library assets into Google's space, perhaps there are ways to bring Google assets like Scholar and Books into the library space (a Google Books/WorldCat Local integration?).
- Data exchange: if you've ever had to get your data up to OCLC in batch form, you've most likely experienced pain on par with visiting the dentist for a minor procedure. Their procedures for doing things like local data record uploading are horrendously slow and bureaucratic. WorldCat will never truly be a universal catalog for library assets if OCLC can't streamline methods for updating data in WorldCat.
Monday, July 2, 2007
Google Book Search Local
So here's an idea...
The Google AJAX search API makes it pretty darn easy to create a customized Google Book Search for your own web page. The API will return an identifier (which is typically an ISBN) for the book, among other metadata in results lists. Why not use a little JSON and JQuery to figure out whether or not your library holds the item and insert that information w/ link in the results? A database of your library and/or union catalog holdings would facilitate the task.
This would create a nicely localized version of Book Search for your library.
The Google AJAX search API makes it pretty darn easy to create a customized Google Book Search for your own web page. The API will return an identifier (which is typically an ISBN) for the book, among other metadata in results lists. Why not use a little JSON and JQuery to figure out whether or not your library holds the item and insert that information w/ link in the results? A database of your library and/or union catalog holdings would facilitate the task.
This would create a nicely localized version of Book Search for your library.
Tuesday, May 1, 2007
Giving WorldCat Local a Go
UW (not the great, Badger State UW, rather that lesser institution: the University of Washington) launched WorldCat Local today. I can't say that there are too many surprises to me in the implementation, as it is based on the now familiar WorldCat.org platform.
But a few observations:
I knew that they would be offering fairly direct requesting for items held in the Summit consortium. This works pretty well and, interestingly, even works for me as someone at Lewis & Clark. Even if I come across an item that is held at the UW libraries, I am offered the ability to request it on Summit.
One thing I don't really care for is the display of holding libraries closest to me that is shown when I've selected a book...this just seems irrelevant and confusing to me when I'm a member of the Summit network.
The book that "should" come to the top is probably "Bend, in Central Oregon", which is the main book ABOUT the city Bend, OR...WorldCat Local needs to work on that "aboutness" thing...not sure how. Perhaps they need to be doing more creative things with subject headings or somehow move govt. publications lower in the ranks. Or bring in circulation stats...those would quickly lower govt. docs in the rank.
Interestingly, WorldCat.org seems to have more sensible results when you search for "Bend Oregon"...perhaps they are using more of a public library relevance ranking system that doesn't report all those depository library holdings
Relevance ranking is not an easy thing to do, of course, and is much more than a popularity contest. It's funny how library holdings are a strange take on "popularity."
Another complaint: the facets for authors don't always work very well. Seems like corporate authors without much meaning ("United States") often float to the top. Also, it's hard to browse around the publication date facet.
I don't see many openings for mashups and remixability...no RSS feeds or apis advertised. I have hopes that OCLC will open things up.
The other question that's hard to answer is the degree of local configurability. Generally speaking, it's a pretty busy display when looking at a particular title, but it would be nice to think it could be configured locally and streamlined.
I applaud the inclusion of articles and hope this expands. Bringing on board large aggregations of articles could be great. Better resolver integration would be nice as more articles appear.
Overall, this is a pretty good first shot at an OPAC product by the behemoth OCLC.
But a few observations:
I knew that they would be offering fairly direct requesting for items held in the Summit consortium. This works pretty well and, interestingly, even works for me as someone at Lewis & Clark. Even if I come across an item that is held at the UW libraries, I am offered the ability to request it on Summit.
One thing I don't really care for is the display of holding libraries closest to me that is shown when I've selected a book...this just seems irrelevant and confusing to me when I'm a member of the Summit network.
The relevance ranking seems to be based a great deal on how many libraries hold an item. This is definitely a good direction to go and could be likened to Google PageRank. But it doesn't always work well. When I searched for "Bend Oregon", for example, the top hit is an EPA publication: "Pressure and vacuum sewer demonstration project Bend, Oregon". I also got lots of references to government documents with the title: "Amending the Bend Pine Nursery Land Conveyance Act..."--it's held by like 189 libraries. (I think this offers some hint of the redundancy involved in acquiring and cataloging government documents across libraries when these types of documents are often rarely used and available openly on the web).
The book that "should" come to the top is probably "Bend, in Central Oregon", which is the main book ABOUT the city Bend, OR...WorldCat Local needs to work on that "aboutness" thing...not sure how. Perhaps they need to be doing more creative things with subject headings or somehow move govt. publications lower in the ranks. Or bring in circulation stats...those would quickly lower govt. docs in the rank.
Interestingly, WorldCat.org seems to have more sensible results when you search for "Bend Oregon"...perhaps they are using more of a public library relevance ranking system that doesn't report all those depository library holdings
Relevance ranking is not an easy thing to do, of course, and is much more than a popularity contest. It's funny how library holdings are a strange take on "popularity."
Another complaint: the facets for authors don't always work very well. Seems like corporate authors without much meaning ("United States") often float to the top. Also, it's hard to browse around the publication date facet.
I don't see many openings for mashups and remixability...no RSS feeds or apis advertised. I have hopes that OCLC will open things up.
The other question that's hard to answer is the degree of local configurability. Generally speaking, it's a pretty busy display when looking at a particular title, but it would be nice to think it could be configured locally and streamlined.
I applaud the inclusion of articles and hope this expands. Bringing on board large aggregations of articles could be great. Better resolver integration would be nice as more articles appear.
Overall, this is a pretty good first shot at an OPAC product by the behemoth OCLC.
Subscribe to:
Posts (Atom)